
Jev Arena
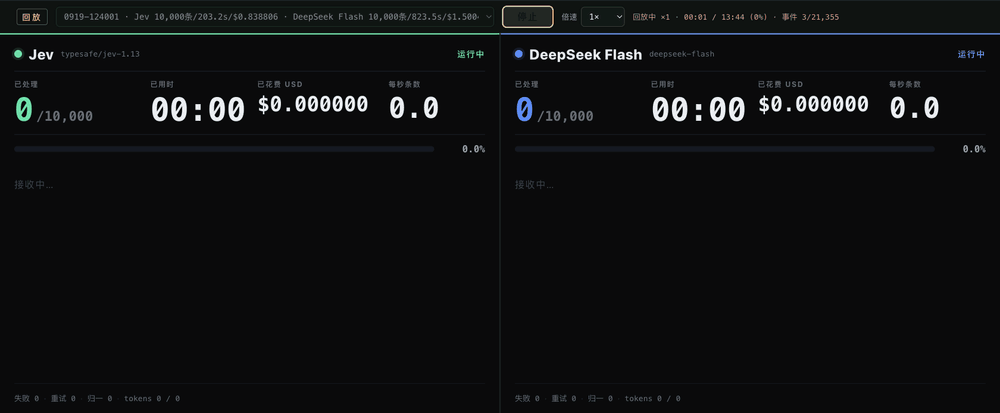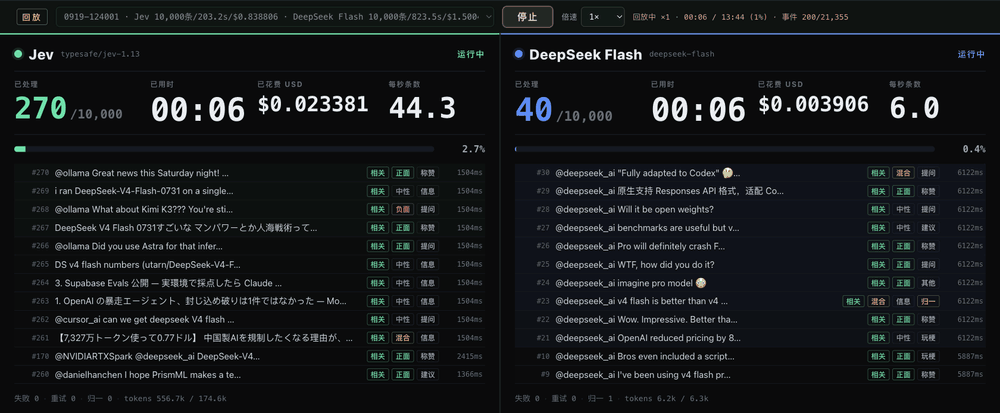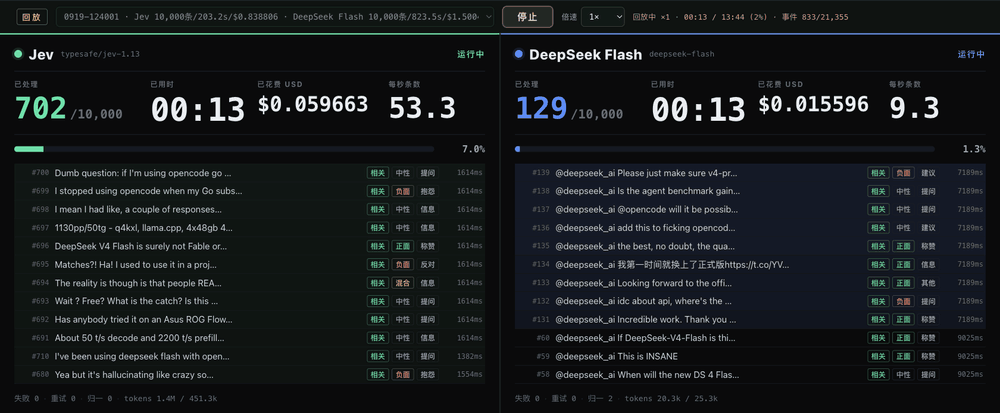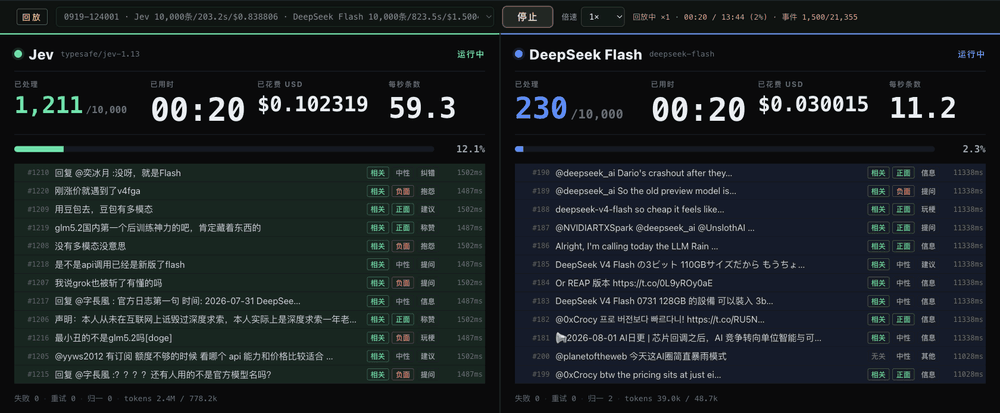
A benchmark harness that compares Jev and DeepSeek on comment-labeling tasks and records per-item outcomes, usage, cost, and latency.
Added to Jevfast
A benchmark harness that compares Jev and DeepSeek on comment-labeling tasks and records per-item outcomes, usage, cost, and latency.
For each comment in a batch, Jev answers a fixed family of typed questions about relevance, sentiment, intent, aspects, and emotions, plus a sentiment score. The host maps answers into labels and derives evidence quotes mechanically from source text.
Is the representative comment about or evaluating an AI model or product?
A batch of source comments/reviews. Each comment gets the same set of classification questions; IDs include the index of that comment in the batch.
Which overall attitude does the comment express?
A batch of source comments/reviews. Each comment gets the same set of classification questions; IDs include the index of that comment in the batch.
What is the comment’s main intent?
A batch of source comments/reviews. Each comment gets the same set of classification questions; IDs include the index of that comment in the batch.
Which source-defined sentiment tier best fits the comment?
A batch of source comments/reviews. Each comment gets the same set of classification questions; IDs include the index of that comment in the batch.
The operator selects a dataset and run configuration.
The runner groups comments and generates per-comment question IDs.
Jev and the comparison backend label each batch; oversized or failed batches follow the documented split and retry handling.
The runner stores labels and events, then builds comparison, coverage, usage, cost, and latency reports.
The arena evaluates structured decisions at batch scale and preserves failure, cost, latency, and labeling evidence alongside comparative outcomes.