
 New
JevHarness
LLM-authored task-specific Jev harnesses with optional full-trajectory reward reflection and GEPA evolution.
Added to Jevfast
NewLLM-authored task-specific Jev harnesses with optional full-trajectory reward reflection and GEPA evolution.
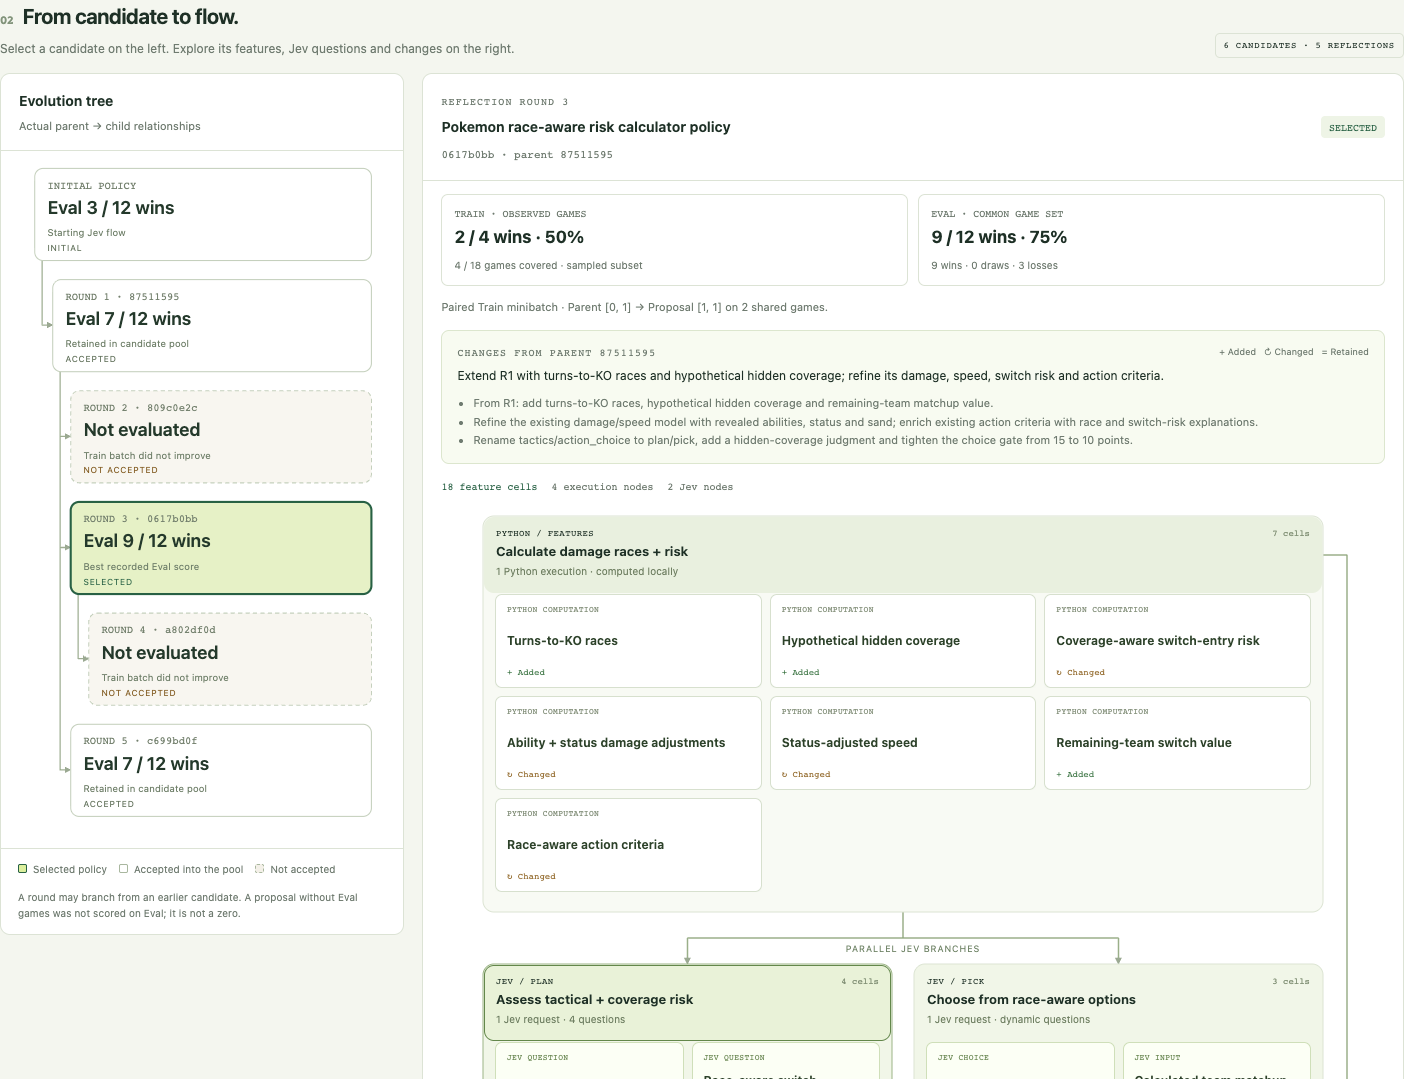
An authoring LLM creates a task-specific harness that extracts features from task observations, builds a Jev state and typed questions, and combines the answers into actions. After selection, the harness runs its fixed code and Jev calls without invoking the authoring LLM for each decision.
Choose the single action most likely to win the whole battle, not only this turn.
Recorded Pokémon turn-12 battle state, recent battle log, HP and move estimates.
Specify observations, legal actions, side effects, and task scoring separately from the decision harness.
Use an LLM during development to create feature code, state, Jev questions, control flow, and memory.
Execute the selected harness against task observations, combining computed features and Jev judgments into actions.
Review full traces and rewards; reflection can propose revisions, which are evaluated before a harness is selected and frozen.
It separates deep strategy authoring from fast runtime judgments and retains complete execution traces for optional reward reflection and harness evolution. The README describes the Pokémon result as selection-Eval performance, not an independent unseen-game estimate.